This week: my agents pitched me story ideas, and I said no to one of them
A three-agent editorial team, an 80% price cut, a credit card for your agent, and the routing audit that ties it all together.
Some of what you're about to read was scouted by machines. Every ruling on it was mine, including one where I overruled my own editor. That's not a confession. It's the whole point of this issue.
On the bench
This week I stood up an editorial research team for this newsletter. Three agents, three jobs: a scout that sweeps the last few weeks of AI news against a fixed list of subjects, an editor that groups and scores what the scout finds against a written rubric, and a researcher that verifies the evidence behind anything the editor scores high. The output isn't a draft. It's a queue of scored, sourced idea packages waiting for me to approve or reject them. Nothing publishes, nothing sends. The system's terminal output is a pile of ideas in front of a human.
One deliberate choice did most of the work: each role runs on a different AI model from a different company. Different model families provide different outputs and have different taste. The scout is enthusiastic by design. The editor is picky by design. The researcher trusts neither of them.
That choice paid for itself on the very first run. The editor scored an idea about agent security high, claiming nobody had covered the angle. It was wrong. I published that exact lesson on July 22. The researcher, a different model with different taste, caught the repeat downstream and recommended archiving the card. My editor missed it; my fact-checker caught it. If both jobs ran on the same model, they'd share the same blind spots, and I'd have paid for the same mistake twice.
The other thing I noticed: the finished idea packages sat in the approval queue for over a day because I was busy running my actual businesses. A day of latency, waiting on me. That's not a flaw. That's the design working. The expensive resource in this system is my judgment, and the whole pipeline exists to spend it on decisions instead of on scrolling feeds. Ideas can wait a day. Bad ideas shipping without review can't be un-shipped.
Two of the three signals below came out of that queue. The third is one I approved over my editor's objection, and I'll tell you why when we get there.
The gauges
The price cut is a routing audit, not a new default
Last week I flagged OpenAI's GPT-5.6 price cuts as news: Luna down 80% to $0.20 per million input tokens and $1.20 per million output, Terra down 20%. A week of reading the follow-up coverage (CNBC, VentureBeat) confirmed what I suspected: everyone is reporting the discount, and almost nobody is telling operators how to decide what to move. Also worth noticing what didn't move: Sol, the top model, stayed at full price, and its new Fast mode costs more.
Should you pay attention? Yes, and differently than last week. The news was the price. The decision is the routing, and the routing advice floating around is wrong.
My position: "easy" is the wrong routing label. "Cheap to be wrong" is the right one. The mistake I keep seeing is routing by task difficulty: hard task gets the smart model, easy task gets the cheap one. But a routine task can deserve your most expensive model when an error is costly, and a complex task can run on the cheap tier when the output is reviewable and reversible. OpenAI's own pricing note says the quiet part: the right model can change from one step of a workflow to the next. So don't switch defaults because a chart moved. Audit. Find your highest-volume step, ask what a mistake there actually costs you, and test the cheap tier only where failure is cheap and recoverable. One caveat the coverage skips: nobody has published small-business savings numbers yet. The named wins are all AI-native companies. Treat this as a test worth running, not a result you've been promised.
Your agent can have a credit card now. That doesn't mean it should.
Last week I told you the payment rails were arriving. This week the instruction manual showed up. Corpay's Agent Card announcement was the what; a detailed explainer published Monday is the how: per-transaction caps, merchant category allow-lists, velocity rules, geofencing, time-bound expiry, instant revocation. Visa and Mastercard are both building network-level versions.
Should you pay attention? To the controls, yes, because they're about to be pitched at you as the reason it's now safe to hand your agent a card. Worth knowing both sources here are vendors selling the picks and shovels; nobody has published data on operators actually using these cards or what went wrong when they did.
My position: the controls are real and they're well designed, but they answer the wrong question. A spending cap can block an out-of-policy purchase. It cannot make an in-policy purchase a good decision. $200 at an approved merchant can still be the wrong vendor, the wrong quantity, or a subscription you already have. Guardrails limit damage. They don't supply judgment. For most small operations the honest first policy is no card yet: the agent researches, compares, and assembles the purchase with its evidence, and a person clicks buy. That's not timidity, and it's not anti-automation. It's sequencing. If a purchase is so standardized that your judgment adds nothing, fine: scope one card to that one purchase, one merchant, small ceiling, short expiry, and review the receipts. Everything else keeps a human at checkout. I wrote two weeks ago about giving agents authority in rope, not walls. A card is a lot of rope.
93% say AI helps them. 14% actually run on it.
Goldman Sachs' 10,000 Small Businesses survey from March: 76% of small businesses now use AI, 93% of users say it has a positive impact, and only 14% say it's fully embedded in core operations. Meanwhile small-business voices like Daniel Sweet are pushing back on the "replace your employees with AI" pitch, arguing the real fit today is assisted automation.
Should you pay attention? Yes, because you're probably standing in that gap right now, and so is everyone you compete with.
My position: this was the idea I approved over my editor's objection. It flagged the topic as too close to a lesson I published in July about bounded autonomy, and on the prescription it was right. But the data is new, and the data is the story. A 93-to-14 gap isn't a technology problem; the tech demonstrably works for the people using it. It's an authority-design problem. Businesses got value from AI as a tool, and now they're stalled at the doorway between "it helps me work" and "it does work I trust." You don't cross that doorway with a headcount replacement plan. You cross it with one task, fully specified, with a human review on the output, run enough times that the review stops finding problems. Then the next task. The 14% aren't smarter than you. They just started smaller than the sales pitch told them to.
Your move
Ten minutes, two columns. This one feeds directly into this week's playbook.
- List every recurring step in your business where an AI model or agent does the work. Drafting replies, sorting documents, research summaries, classification, review passes. Every step, one line each.
- Next to each, write what one mistake there actually costs. Not the odds of a mistake, the cost of one: an annoyed customer, a wrong number in a quote, ten wasted minutes, a compliance problem.
- Mark each line cheap-to-be-wrong or expensive-to-be-wrong. Be honest. "Embarrassing" counts as expensive.
- Circle the mismatches: expensive models doing cheap-to-be-wrong work, and, far more dangerous, cheap models doing expensive-to-be-wrong work.
Most operators find at least one of each. The first kind is burning money. The second kind is borrowing it.
The meme
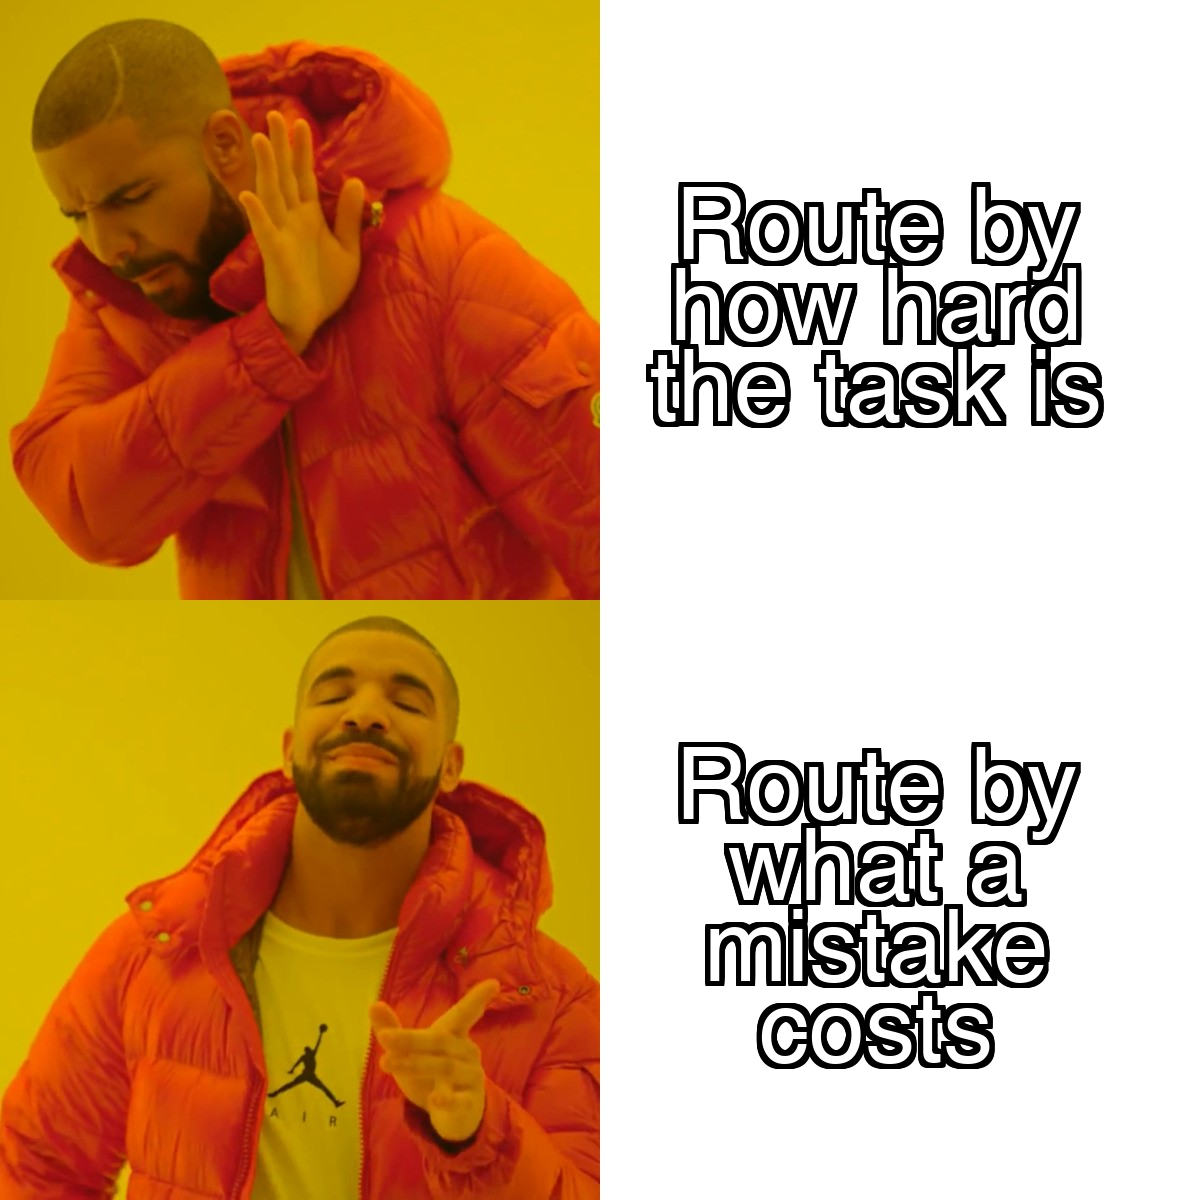
The model doesn't need to know how hard the task is. You need to know what it costs when it's wrong.
The playbook: the monthly routing audit
Operators: the price cut is the trigger, but this playbook outlives it. Prices moved three weeks after GPT-5.6 launched and they'll move again. What you want is not a new default model. It's a repeatable audit that re-prices your workflow every time the market re-prices the models, plus an acceptance test that tells you when a cheaper tier is safe. Build it once, run it monthly, hand the whole thing to your agent.
1. Inventory before opinions
Your Your-move list is the input. For each recurring AI step, you need four columns:
- Cost of error: what one wrong output costs, in dollars, relationship damage, or cleanup time. Write an actual estimate, not "low."
- Urgency: does this step block a person or a customer while it runs? Waiting-room steps can use slower, cheaper models. Real-time steps may need fast ones.
- Volume: calls per week, times average tokens if you have them. This is where the money is. A step that runs 400 times a week matters more than one that runs 4.
- Recovery path: if the output is wrong, who catches it and how? "A person reviews it before it goes anywhere" is a recovery path. "It posts automatically" is not.
The four columns are the whole trick. Difficulty is deliberately not one of them. A hard task with a human reviewer and low stakes is a fine candidate for a cheap model. A trivial task that touches a customer with no review is not.
2. The routing rule
One sentence: the cheapest model that clears the acceptance test, but only where failure is cheap or caught.
In practice that produces three lanes:
- Cheap lane: high volume, low cost of error, recovery path exists. Route to the cheapest capable tier. This is where the July 30 cut pays you.
- Default lane: moderate stakes, reviewable output. Mid tier. Most of your steps live here and that's fine.
- Expensive lane: anything touching money, customers, commitments, or permanent records without review. Best model you can afford, and honestly, this lane should also have a human in it. A model upgrade is not a substitute for a reviewer on irreversible steps.
Steps only move lanes on evidence, never on a price chart alone.
3. The acceptance test
Before any step moves to a cheaper model, it has to pass the same bar the current model passes. Not "seems fine." A test.
- Collect 20 to 50 real, recent inputs for the step. Real ones, with the mess left in. Your weird customers, your edge cases, the email written entirely in lowercase.
- Define pass/fail before you run anything. What does an acceptable output look like? What's an automatic fail? Write it down; you're going to hand it to an agent.
- Run both models on the same inputs. Compare against your written criteria, not against each other's style.
- The cheaper model needs to match or beat the incumbent on your fail conditions. Ties on quality go to the cheaper model. Any new failure class the old model didn't have is a no, regardless of savings.
- Record the result with dates and model versions. Next month's audit starts from this file.
If you can't define pass/fail for a step, that's a finding: you've been running a step with no quality bar on any model. Fix that before you touch routing.
4. The rollback condition
Every routing change ships with its undo written down first: the exact symptom that reverses it, who's allowed to trigger the reversal, and how fast it happens. "If the review catches two bad outputs in a week, this step goes back to the mid tier same-day, no meeting required." Without this, cheap-lane mistakes turn into debates. With it, they turn into a config change.
And put a monthly date on the calendar. Fifteen minutes: re-check prices, re-run the acceptance file on anything you're tempted to move, retire steps that no longer run. The audit is the durable asset. The routing table is just this month's output.
5. Hand it to your agent
Copy this to the agent that helps run your operation:
Build and maintain a model-routing audit for my recurring AI workflow steps.

1. Inventory: list every recurring step where a model or agent produces
   output. For each, record: cost of one error (estimate honestly),
   urgency (does a person or customer wait on it), weekly volume, and
   recovery path (who or what catches a bad output before it matters).
2. Lanes: propose cheap / default / expensive lane assignments using this
   rule: the cheapest model that clears the acceptance test, but only
   where failure is cheap or caught. Never route steps that touch money,
   customers, commitments, or permanent records to an unreviewed cheap
   lane, regardless of savings.
3. Acceptance tests: for each step proposed to move cheaper, build a test
   set of 20-50 real recent inputs, write pass/fail criteria with me
   before running, run incumbent and candidate on identical inputs, and
   report failures by class. A new failure class the incumbent didn't
   have is an automatic no.
4. Rollback: for every approved change, record the reversal symptom,
   who can trigger it, and the reversal deadline before the change
   goes live.
5. Re-run monthly: refresh prices, re-run stored acceptance sets on
   proposed moves, and flag steps whose volume or stakes have changed.
   Keep all results in one dated file I can read in five minutes.

Propose changes to me. Do not change any live routing without my
approval, and do not touch steps that send, spend, or publish.
That last paragraph is the part most people skip. The audit is the agent's job. The routing decision is yours. Same division of labor as my editorial queue: the machines do the sweep, the human does the ruling.
What not to build
Skip per-request dynamic routing where a classifier picks a model on the fly for each call. It's a real technique, and at small-business scale it's an over-build: you'll spend more debugging the router than the router saves, and your acceptance story turns to mush because every request might hit a different model. Lane-per-step, reviewed monthly, is boring and auditable. Boring and auditable is the brand.
Steal this: pick your single highest-volume AI step today. Write down what one error there costs and who would catch it. If the answer is "cheap and someone catches it," run the acceptance test against the newly discounted tier this week. That one test either saves you real money every month or proves your current spend is justified. Both are wins.
Hit reply and tell me what's on your bench this week. I read every one.
— Justin